Marcus manages the day-to-day editorial workflow across all brands, coordinating coverage assignments and ensuring editorial standards are met. He previously served as city editor at the Pioneer Press and holds a degree in Political Science from Carleton College.
Agentic AI / Generative AI
When One GPU Isn’t Enough: Serving GLM-5.3 Across Two NVIDIA DGX Stations with vLLM
Nov 13, 2026
By
Fatima Fall
Like
Discuss (0)
L
T
F
R
E
AI-Generated Summary
GLM-5.3 NVFP4
, a quantized mixture-of-experts model with 753 billion parameters and 40 billion activated per token, requires about 464 GB of GPU memory, exceeding the 252 GB HBM3e on a single GB300 GPU.
Two NVIDIA DGX Stations connected over ConnectX-8 RDMA serve the model through one OpenAI-compatible endpoint using tensor parallelism (TP=2), with each GPU holding and computing roughly half the weights.
vLLM launches a distributed service across both Stations, enabling multi-token prediction, FP8 KV-cache storage, and prefix caching to maximize throughput under concurrent load.
AIPerf benchmarks on the SPEED-Bench Coding dataset show overall output throughput peaking at 607.8 tokens per second at concurrency 16, then falling to 385.0 tokens per second at concurrency 32 with mean request latency of 453.5 seconds.
Next Steps
Follow the
Connect Two DGX Stations playbook
to link and validate the hardware before deployment.
Review the
NVIDIA Local AI recipe repository
for the latest recommended configurations.
Connect an application using the
vLLM serving documentation
and rerun AIPerf with custom prompts to find the optimal concurrency for the workload.
Powered by NVIDIA Nemotron. AI-generated content may summarize information incompletely. Verify important information.
Learn more
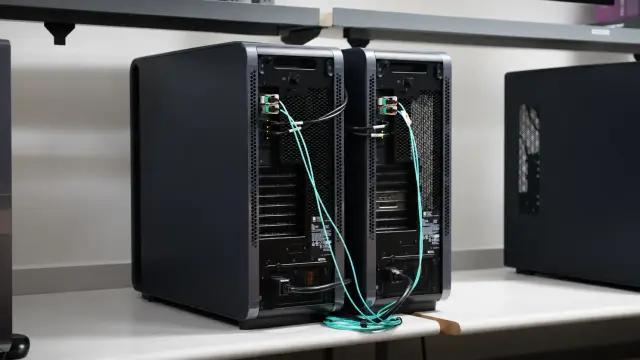
Running a frontier-scale model locally means keeping all its weights in GPU memory; the largest models no longer fit on one machine. Two NVIDIA DGX Stations connected over ConnectX-8 RDMA serve one model through a single endpoint, with tensor parallelism splitting the model weights and computation across both GPUs.
The NVIDIA
GLM-5.3 NVFP4
model, a quantized version of
Z.ai
’s mixture-of-experts (MoE) model, has 753 billion parameters, with 40 billion activated per token. Sparse activation reduces computation, but all model weights still need to remain available because each token can be routed to different experts. At about 464 GB, the checkpoint exceeds the 252 GB of HBM3e on a single GB300 GPU. This tutorial uses two DGX Stations to keep the weights in GPU memory, with CPU weight offload disabled.
Before starting, connect the two Stations with the
Connect Two DGX Stations playbook
.
This post shows how to serve GLM-5.3 locally across two NVIDIA DGX Stations with vLLM, send a request, and measure behavior under concurrent load. Tensor parallelism (TP=2) splits the model’s tensors across the two GB300 GPUs. Both Stations compute every request, and Station A returns the answer through one OpenAI-compatible API. By the end, you’ll have a working endpoint and a baseline for how it behaves under load.
Prerequisites
Two GB300 DGX Stations running Linux, connected and validated with the
Connect Two DGX Stations playbook
, including its GPU-memory RDMA test on both rails.
SSH and sudo access on both Stations with the same Linux username. Docker and the NVIDIA Container Toolkit come preinstalled with the
DGX Station software stack
. Allow outbound access to the container registry, Hugging Face, and package repositories.
At least 464 GB of free disk space on each Station for its copy of the checkpoint, plus room for the vLLM container image and temporary files.
Acceptance of the NVIDIA Open Model Agreement and the original GLM-5.3 license terms, listed on the
model card
. SPEED-Bench is governed by the
NVIDIA Evaluation Dataset License Agreement
.
A Hugging Face account and read access token, with access to the gated
cais/hle
dataset: sign in, open its page, and select
Agree and access repository
. Step 5 downloads SPEED-Bench prompts from this dataset.
The companion video follows the same workflow.
Step 1. Prepare the two Stations
This tutorial uses a separate computer, such as your laptop, to manage both Stations. Start by opening an SSH session to each Station from that computer. Alternatively, work from a local terminal on each Station. Run every command in this step on both Stations unless it starts with “On A.”
The two Stations run the same container and checkpoint in different roles: Station A (rank 0) hosts the API, and Station B (rank 1) runs only a worker, with no API server.
First, check Docker access and collect the network values you’ll use later:
docker version
ibdev2netdev
ip -br addr
Note:
If the
docker version
output has no
Server
section, the client cannot reach the Docker daemon. If the error is
permission denied
, follow the
Docker post-installation procedure
: add your user to the
docker
group with
sudo usermod -aG docker "$USER"
, run
exit
, then reconnect and rerun
docker version
. The
docker
group grants root-level privileges.
The
ibdev2netdev
output lists the two direct rails,
cx8r0
and
cx8r1
. Pick one for serving traffic, for example
cx8r1
, and note two things for it on each Station:
Its RDMA device
, on the
ibdev2netdev
line that ends with the rail’s name. In
mlx5_1 port 1 ==> cx8r1 (Up)
, the device is
mlx5_1
.
Its IPv4 address
, on the
ip -br addr
line that starts with the rail’s name. In
cx8r1 UP 192.168.101.1/24
, the address is
192.168.101.1
.
The rail name and device are the same on both Stations; only the IPv4 address differs.
Next, create
~/glm53.env
on each Station. This file stores the values that later commands use:
nano ~/glm53.env
Paste the following block and replace each
<...>
placeholder, keeping the quotes, with the values you noted.
RANK="" # RANK="0" on Station A, RANK="1" on Station B
HEAD_IP="" # IPv4 address you noted on Station A; same in both files
WORKER_IP="" # IPv4 address you noted on Station B; same in both files
RAIL_IFACE="" # Rail you picked, for example cx8r1; same in both files
RAIL_HCA="" # RDMA device you noted, for example mlx5_1; same in both files
IMG=vllm/vllm-openai:v0.30.0-aarch64
IMG+=@sha256:4864d46625cbc3307623e29ac742030655e27249feba7b97ec925ce4cc4dfb56
MODEL_REPO=nvidia/GLM-5.3-NVFP4
MODEL_REV=e3b8f9f2fad29727dfa95e766c5cac18ea1414bf
MODEL_HOST="$HOME/models/GLM-5.3-NVFP4"
CONTAINER=glm53-full
PORT=8000
if [ "$RANK" = 0 ]; then
NODE_IP=$HEAD_IP; PEER_IP=$WORKER_IP
else
NODE_IP=$WORKER_IP; PEER_IP=$HEAD_IP
fi
GPU_UUID=$(nvidia-smi --query-gpu=uuid,name --format=csv,noheader |
awk -F, '$2 ~ /GB300/ {gsub(/ /,"",$1); print $1; exit}')
For example, with the default addresses on
cx8r1
, Station A’s file starts like this. Station B’s file is identical except for
RANK="1"
:
RANK="0"
HEAD_IP="192.168.101.1"
WORKER_IP="192.168.101.2"
RAIL_IFACE="cx8r1"
RAIL_HCA="mlx5_1"
MODEL_HOST
is built from your home directory, and Step 2 copies the checkpoint over SSH to the same path on Station B.
Note:
Later steps start with
source ~/glm53.env
to load these values.
Run this command again whenever you open a new SSH session.
On both Stations, load the values and check storage, connectivity, and baseline memory:
source ~/glm53.env
mkdir -p "$MODEL_HOST" && df -h "$MODEL_HOST"
ethtool "$RAIL_IFACE"
ip link show dev "$RAIL_IFACE"
ping -I "$RAIL_IFACE" -M do -s 8972 -c 3 "$PEER_IP"
timedatectl show -p NTPSynchronized --value
nvidia-smi
These checks catch cabling and addressing mistakes before they surface as NCCL timeouts. Expect a
400000Mb/s
link, MTU 9000, successful jumbo-frame pings, and synchronized time.
nvidia-smi
should show no compute processes on the GB300. On a Station with a display GPU, Xorg can appear on both GPUs with a few MiB.
Tip:
Note the GPU memory use shown by
nvidia-smi
; Step 4 compares it with the loaded model.
Step 2 copies the checkpoint from A to B over SSH, so A needs passwordless access to B. On A, create a key without a